Live labs & production systems
Running systems, retired systems, and the repos behind both.
Nothing here is a mockup. These are public systems I built and operate — the platform and reliability evidence behind the consulting. One cluster is answering the request you just made; one was designed, operated, and shut down when the GPU bill stopped being worth it. Both trees are public, and each card links the exact directory worth reading.
Here from a repository link: the cluster those manifests deploy is the one answering this request. If you want a second opinion on yours, the first 45 minutes are free.
01 / Hybrid Kubernetes
Three nodes, no managed control plane — and this page runs on it.
A cluster bootstrapped from bare nodes with kubeadm: an amd64 control plane behind a Cilium Gateway, a Raspberry Pi carrying the Cloudflare tunnel, and a cloud worker in Atlanta — stitched together over WireGuard instead of a LAN, reconciled from Git.
Kubernetes / GitOps Live
sirius-homek8s — six Flux Kustomizations, all Ready
Cloudflare terminates TLS and carries every public request through a cloudflared tunnel
on rpi to the Cilium Gateway on siriussec. No cloud load
balancer, no NodePort exposure: the tunnel is the only public ingress.
- Three nodes —
siriussec(amd64 control plane),rpi(arm64 traffic hub),linode(cloud worker) - WireGuard mesh in
10.10.0.0/24; Cilium routes pod traffic natively, no VXLAN overlay, kube-proxy removed - Gateway API HTTPRoutes onto Cilium's eBPF datapath; Cloudflare Tunnel as sole ingress
- Flux CD — six Kustomizations
Ready=True - CloudNativePG
postgresql:16for Forgejo and one portal - Multi-arch CI runners building the images this Deployment rolls — including this site
- 169 commits on
master, public on Forgejo
- Flux sync root
- Cilium release, values and BPF config
- Cilium Gateway definition
- This site's Deployment, Service and HTTPRoute
- Cluster overview write-up
This page is served from that cluster — the pod answering you is Flux-managed in forgejo.siriusdevops.com/sirius/homek8s.
02 / Retired GPU platform
AgentForge — a GitOps GPU platform. Designed, run, shut down.
A cloud-native platform for high-throughput vLLM inference across three GPU tiers, 100% Git-driven via Terraform + Flux CD, with KEDA HTTP scale-to-zero that took idle GPU pools to zero replicas while weights stayed cached on a PVC.
Cloud platform / GitOps Decommissioned
Cluster destroyed. Terraform and manifests public.
When even the L4 + control-plane bill stopped making sense, the cluster was destroyed. Scale-to-zero was the rehearsal for scale-to-nothing. What survives is the part you actually own: node-pool definitions, vLLM servers, KEDA objects, NetworkPolicies and the Flux wiring that applied them.
- vLLM serving Qwen 3.x on L4 / RTX PRO 6000 / A100 80GB spot pools
- KEDA HTTPScaledObject at
replicas.min: 0— idle reasoning capacity costs nothing - Zero-touch GitOps: every change audited and reconciled from Git by Flux CD
- Per-tenant CloudNativePG databases with a pgvector RAG init job per agent
- 1,018 commits on
master, public on Forgejo
- vLLM server manifests (L4, RTX PRO 6000, A100)
- KEDA HTTP scale-to-zero objects
- CloudNativePG + pgvector agent memory
- Terraform: VPC, GKE, GPU node pools
- Flux cluster root
Repo README: “This is not a live cluster.” — forgejo.siriusdevops.com/sirius/gcloud-lab
03 / Raw screens
Actual sessions. Not mockups.
Unretouched terminal captures from real operations. The vLLM and model-delivery captures are from the GKE lab while it ran; cluster identifiers are redacted and nothing else is retouched.
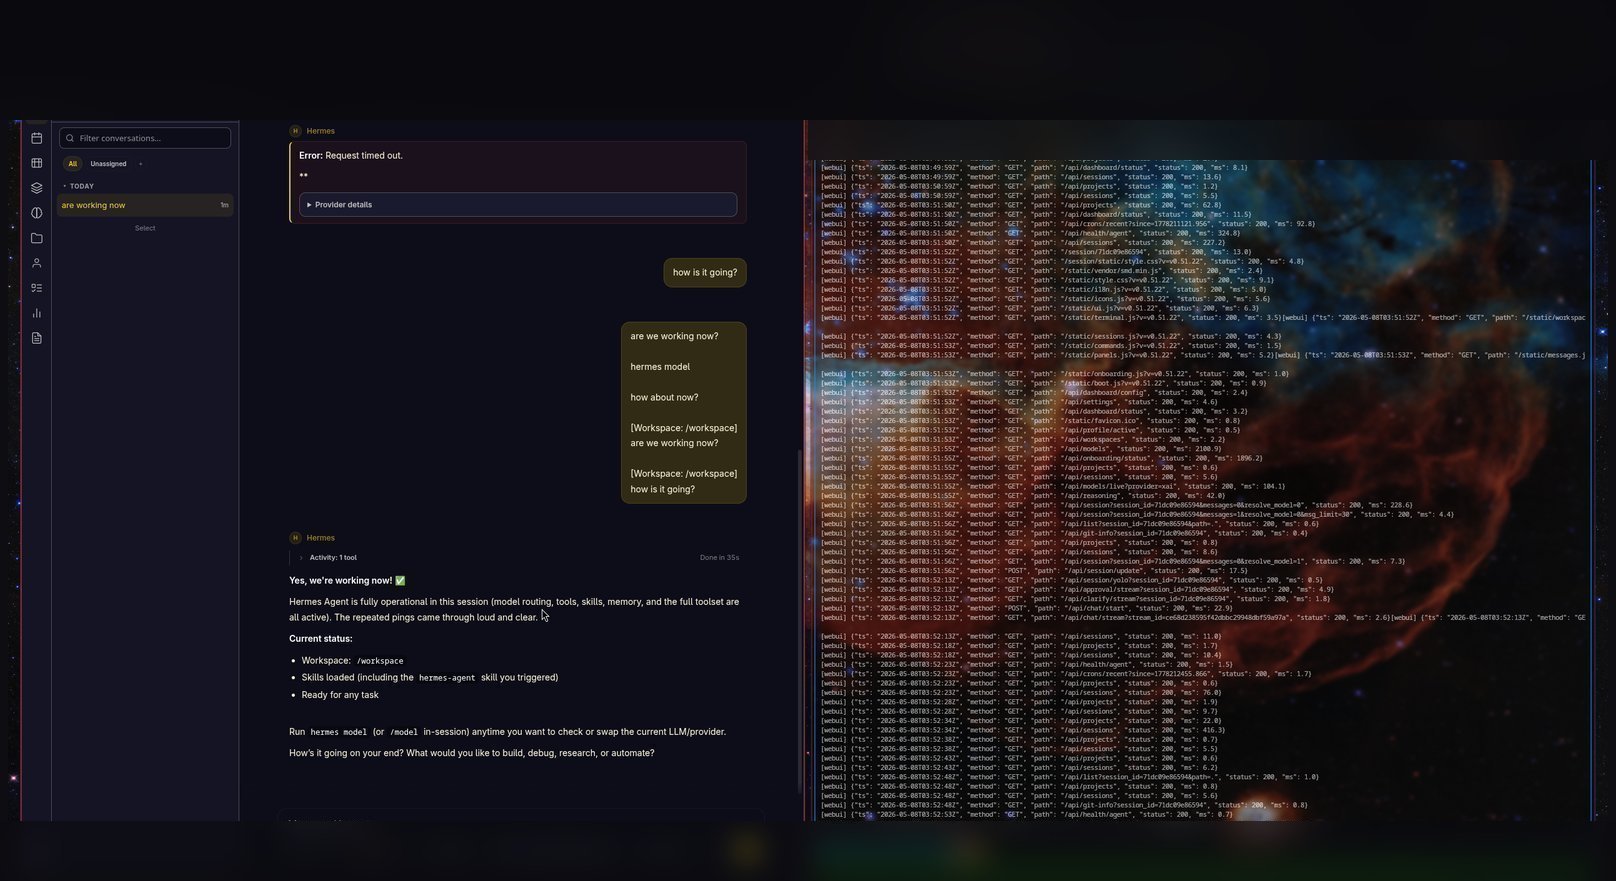
200 from inside the cluster.
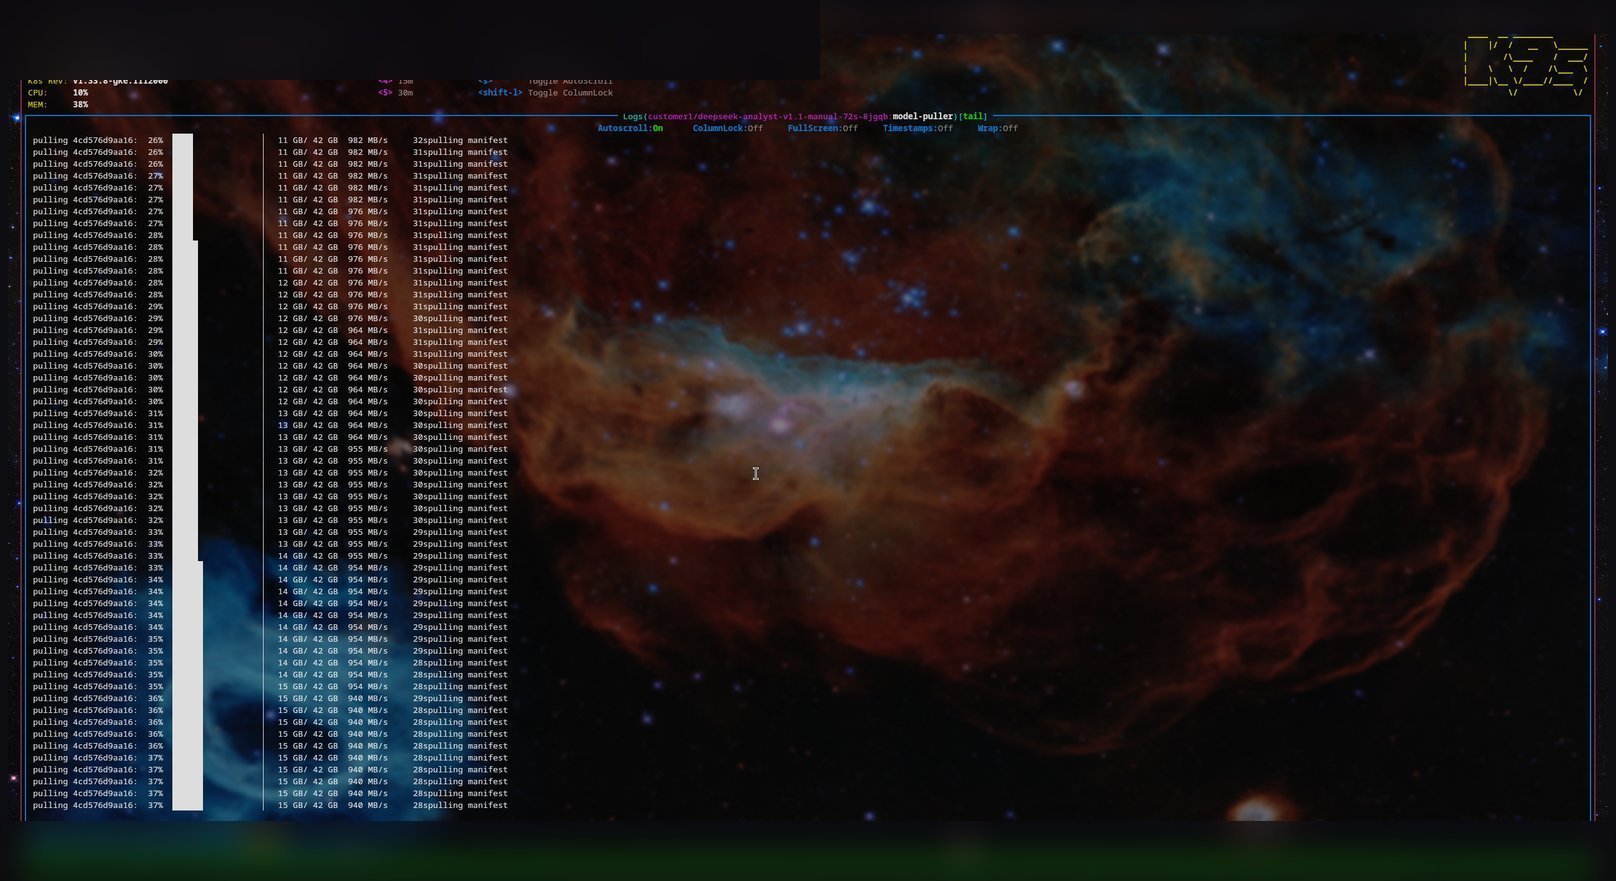
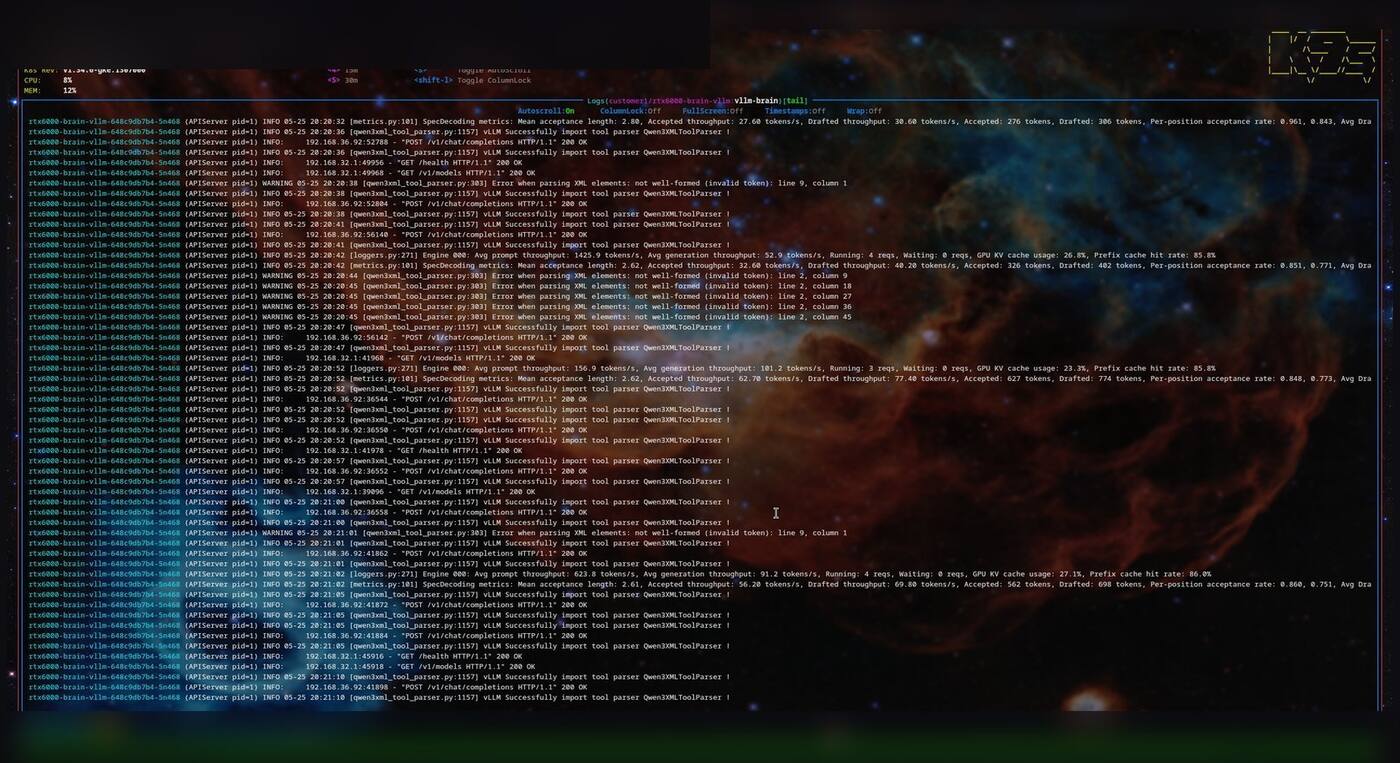
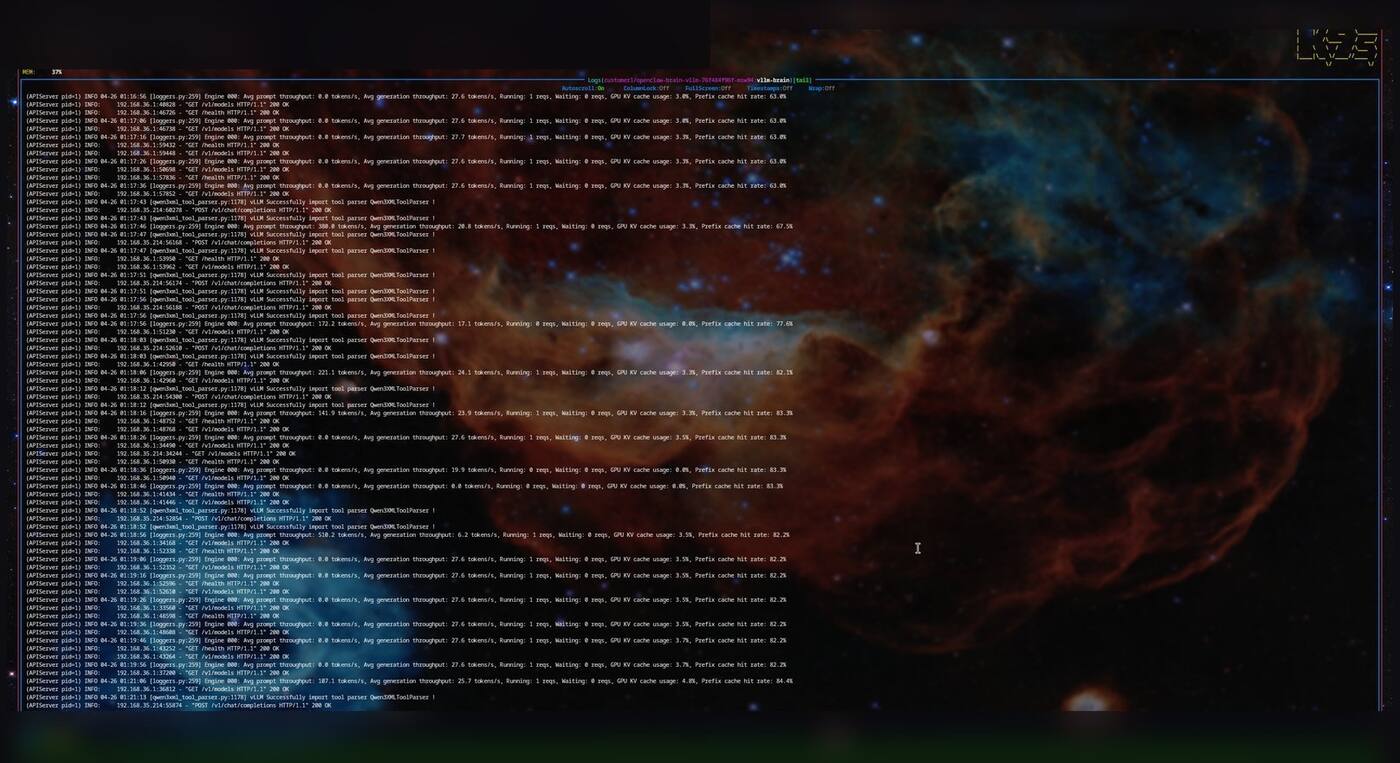
POST /v1/chat/completions requests completing 200 OK while
speculative-decoding acceptance rates stream past — one namespace per tenant,
separated by default-deny NetworkPolicy.
04 / Real-time systems
Event pipelines and agent wiring.
Built on the same lab, framed as integration patterns: how events, model calls and memory fit together when the system has to run unattended.
Event-driven services
Trading platform
Event-driven microservices on GKE — Next.js dashboard, Hyperliquid + Solana execution, Kafka streaming, Redis caching, PostgreSQL. mTLS, cert-manager, default-deny network policies, full CI/CD. Decommissioned with the lab.
Autonomous pipelines
News quant pipeline
Scraped 330+ global news and market feeds, ran a locally served 27B model for analysis, and generated signals — VPC-private, self-running via CronJobs. The pattern is scheduled ingest → local model → structured output.
Agent infrastructure
Hermes-style agents with their own memory
A CloudNativePG cluster per agent, a one-shot RAG init job enabling pgvector, durable memory tables, scheduled backups, and NetworkPolicies that define exactly what a workload may reach. The agent gets a database and a tool list, not the cluster.
05 / Stack
The tools behind the work.
Infrastructure
Orchestration
AI / ML infra
Database
Security
Observability
Next step
Bring your stack. Leave with a punch list.
The 45-minute infrastructure review is free, and useful whether or not you hire me.